JSON-LD Schema Generator
Scaffold valid Organization, Article, or Product JSON-LD that AI engines actually use to cite you.
Quick answer
JSON-LD is a structured-data format for describing entities and page facts. Generate Organization, WebSite, Article or Product markup, then verify it matches the visible content and applicable documentation. Valid syntax does not establish factual accuracy, rich-result eligibility or AI citation.
<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "name": "Acme Inc",
  "url": "https://acme.com",
  "logo": "https://acme.com/logo.png",
  "sameAs": [
    "https://twitter.com/acme",
    "https://github.com/acme"
  ]
}
</script>
Why JSON-LD?
JSON-LD is the structured data format both Google and modern AI crawlers prefer. It's invisible to users but machine-readable — perfect for telling engines what your page is really about.
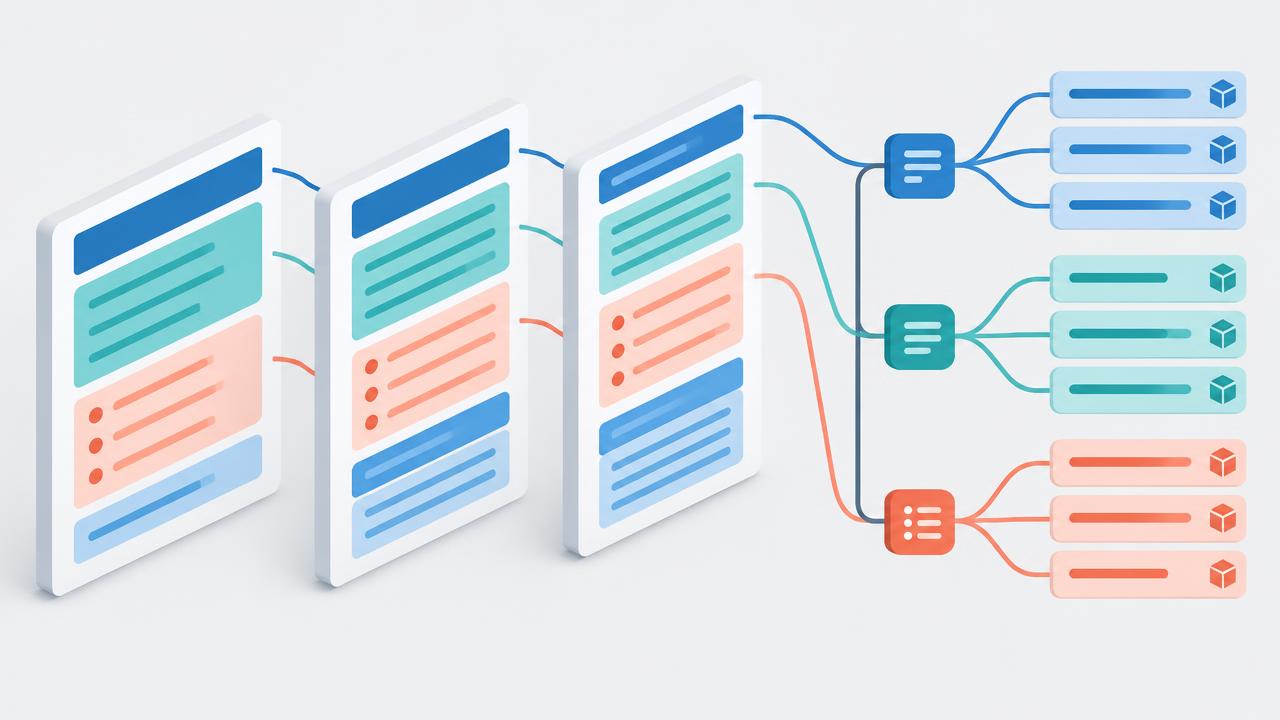
What does structured data do for AI search?
JSON-LD gives machines an explicit graph of the page: who published it, what entity it describes, when it changed, and how its parts relate. That reduces ambiguity during extraction and attribution. It does not force an engine to crawl, trust, rank, or cite the page, so structured data belongs after access and visible content are correct.
Which schema types should you use?
| Page purpose | Primary type | Critical properties |
|---|---|---|
| Company or brand | Organization | name, url, logo, sameAs |
| Editorial content | Article or BlogPosting | headline, author, datePublished, dateModified |
| Named expert | Person | name, jobTitle, affiliation, sameAs |
| Product or software | Product or SoftwareApplication | name, brand, offers, operatingSystem where relevant |
| Visible questions and answers | FAQPage | Question and acceptedAnswer matching the page |
| Visible ordered procedure | HowTo | name and complete ordered steps |
How do you build a consistent entity graph?
- Choose one stable @id for the organization and reuse it across the site.
- Reference that organization as publisher, provider, brand, or affiliation where appropriate.
- Create Person entities only for real named people with visible profiles and credentials.
- Use sameAs for authoritative identity pages, not every social URL you can find.
- Connect each page to its mainEntity or about topics when the relationship is specific and visible.
- Keep names, URLs, logos, dates, prices, and availability synchronized with the page.
What is a safe implementation workflow?
Generate JSON-LD from the same source of truth that renders the visible page. This prevents pricing, availability, dates, FAQ answers, and authorship from diverging. Server-render the script in the final HTML, escape serialized values safely, and avoid adding multiple contradictory entities from plugins and custom code.
{
  "@context": "https://schema.org",
  "@type": "Article",
  "headline": "Structured data for AI search",
  "author": { "@id": "https://example.com/#organization" },
  "datePublished": "2026-09-22",
  "dateModified": "2026-09-22",
  "mainEntityOfPage": "https://example.com/guide"
}
How should structured data be validated?
| Check | Question | Failure example |
|---|---|---|
| Syntax | Is the JSON valid? | Trailing comma or unsafe serialization |
| Vocabulary | Are types and properties valid schema.org terms? | Property used on the wrong type |
| Eligibility | Does the target search feature support this markup? | Expecting an unsupported rich result |
| Parity | Does every material claim match visible content? | Hidden FAQ or different price |
| Delivery | Is the script present in production HTML? | Client-only injection fails for a crawler |
Which structured-data mistakes cause the most harm?
- Adding FAQPage for questions that are not visibly answered on the page.
- Using aggregate ratings or reviews that visitors cannot inspect and verify.
- Publishing stale price, availability, author, or dateModified values.
- Creating different Organization entities with inconsistent names and URLs on each template.
- Marking every page as multiple unrelated primary types.
- Assuming a validator pass proves quality, eligibility, indexing, or citation.
How do you measure the value of schema for AI visibility?
Measure whether engines identify and describe the entity more accurately after markup is corrected. Track validation coverage, extraction errors, search enhancements where applicable, crawler visits, and citation accuracy for a fixed prompt set. Do not attribute a visibility change to schema when content, links, or crawl access changed at the same time.
Practical steps
- 1Identify the page's main entity
Choose the most specific type that matches the visible purpose of the page.
- 2Map visible facts
List the properties visitors can verify and omit unsupported or private claims.
- 3Connect stable identities
Reuse organization and person @id values and carefully selected sameAs references.
- 4Render JSON-LD from shared data
Generate markup from the same content source as the visible page to prevent drift.
- 5Validate in production
Check syntax, vocabulary, parity, and the final server-rendered response after deployment.
More questions answered
- Does schema markup guarantee an AI citation?
- No. Structured data can reduce ambiguity and improve attribution, but citation also depends on crawl access, content quality, relevance, authority, freshness, and the retrieval system used for the query.
- Is JSON-LD better than microdata?
- JSON-LD is usually easier to generate, maintain, and validate without mixing attributes into visible HTML. The important requirement is that the markup accurately describes content visitors can see.
- Can FAQ schema contain answers hidden from visitors?
- It should not. The questions and answers represented in FAQPage markup must match visible page content. Hidden or contradictory answers create a factual-parity problem and may violate search feature guidelines.
- Should every page have Organization schema?
- A stable Organization entity can be referenced sitewide, but avoid duplicating conflicting full definitions. Define the organization consistently and reference its stable @id from relevant pages.
- How often should JSON-LD be audited?
- Audit after template, CMS, pricing, author, product, or navigation changes, and include structured-data validation in routine releases. Time-sensitive properties should update from the same source as visible content.
Want the full picture?
OptimAIze checks structured data, content, crawler access and answer-readiness to help you investigate concrete issues. Technical improvements do not guarantee AI citations.
Run a full GEO + AEO scan on your siteFrequently asked questions
- Which schema types matter most for AI?
- Organization and WebSite for sitewide identity, Article for blog content, Product for e-commerce, and FAQPage for Q&A. These four cover 90% of citation-worthy use cases.
- Where do I install the script?
- Paste the generated <script> block in the <head> of the relevant page. JSON-LD doesn't have to render anything visually — crawlers extract it directly.
- How do I validate it?
- Use Google's Rich Results Test or schema.org's validator. Then run the OptimAIze scanner to confirm AI crawlers can actually fetch and parse the page.
- Can I have multiple JSON-LD blocks on one page?
- Yes. You can stack Organization, BreadcrumbList, and Article on the same page — each in its own <script> tag.
Related free tools
Each one covers a different signal AI engines read before they cite a site.