AI-Aware robots.txt Generator
Explicitly allow or block GPTBot, ClaudeBot, PerplexityBot, Google-Extended and other AI crawlers.
Quick answer
robots.txt expresses crawl preferences to compliant agents. This generator creates user-agent rules and a sitemap directive. Consult each vendor's documentation: training controls and search crawlers have different purposes, and neither an Allow rule nor a training preference guarantees citation. Protect private content with authentication.
Checked = allowed. Unchecked = blocked.
# Generated by OptimAIze — https://optimaize.app/tools/robots-txt-for-ai

User-agent: *
Allow: /

User-agent: GPTBot
Allow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: ChatGPT-User
Allow: /

User-agent: ClaudeBot
Allow: /

User-agent: Claude-Web
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: Perplexity-User
Allow: /

User-agent: Google-Extended
Allow: /

User-agent: Applebot-Extended
Allow: /

User-agent: Bytespider
Allow: /

User-agent: CCBot
Allow: /

User-agent: Meta-ExternalAgent
Allow: /

Sitemap: https://yourdomain.com/sitemap.xml
The new robots.txt rules
A robots.txt that only addresses Googlebot is no longer enough. AI crawlers each use their own user-agent, and they respect the most specific block. Use this generator to set a deliberate policy for every major engine and avoid being silently excluded — or silently scraped.
Recommended defaults
- Allow public resources for compliant search crawlers when discovery is your goal
- Disallow if you're a paywall, exclusive publisher, or proprietary docs site
- Include a
Sitemap:line for crawlers that support it; protect private content with authentication, not robots.txt
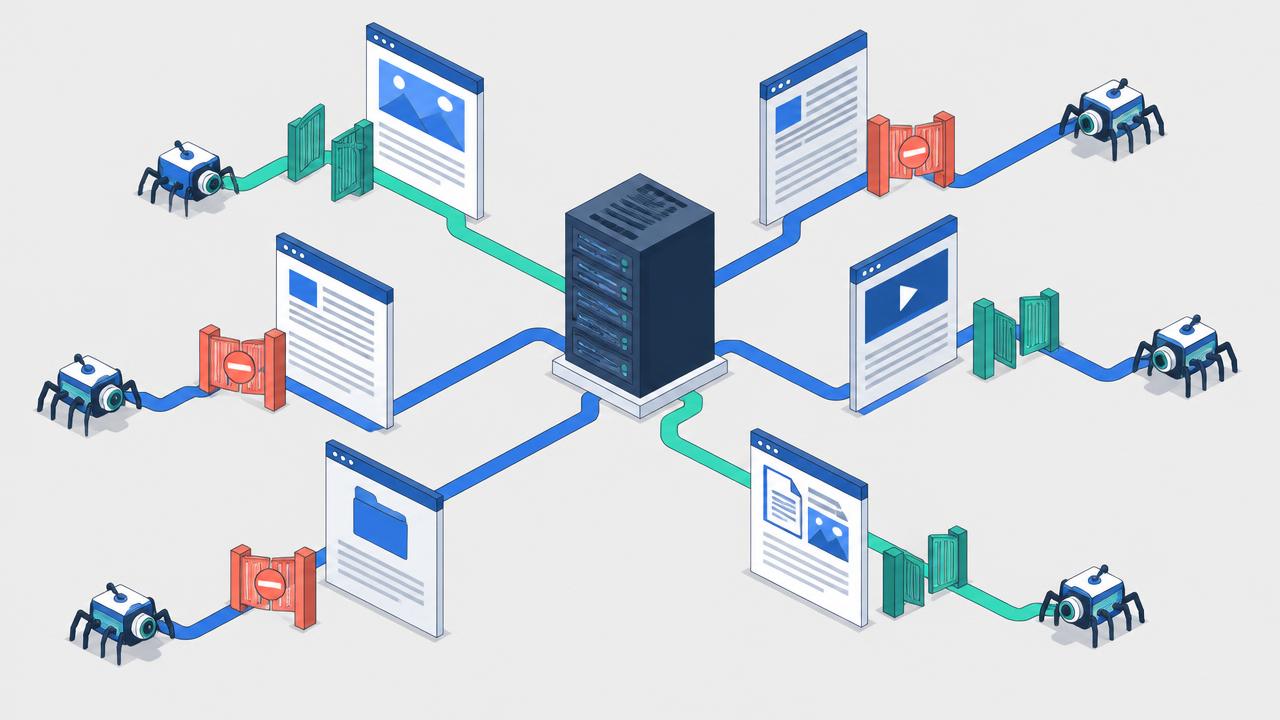
Using AI-Aware robots.txt Generator
robots.txt expresses crawl preferences to compliant agents. This generator creates user-agent rules and a sitemap directive. Consult each vendor's documentation: training controls and search crawlers have different purposes, and neither an Allow rule nor a training preference guarantees citation. Protect private content with authentication.
What should an AI crawler access audit test?
A complete access audit checks four layers in order: declared permission in robots.txt, network access through the CDN or firewall, the final HTTP response after redirects, and the useful HTML available without browser-side JavaScript. Passing one layer does not prove the next one works.
Which crawler names need separate checks?
Do not treat every AI user agent as interchangeable. Search retrieval, user-triggered fetches, and model training can use different crawlers and different controls. Decide your policy by purpose, then test the exact official user-agent token documented by each provider. Crawler names and policies change. Use each provider's current documentation as the authority, and date your audit notes.
What proves the access fix worked?
A fix is verified only when the affected user agent receives a canonical 200 page with the same substantive answer a visitor sees. Save the command, timestamp, headers, and a hash or excerpt of the body. Then confirm a real visit in server logs; synthetic access proves possibility, while logs prove actual crawling.
What should an AI crawler access audit test?
| Layer | Pass condition | Common failure |
|---|---|---|
| robots.txt | The relevant user agent is not disallowed | A wildcard rule overrides an intended allow |
| Network edge | The bot receives the same reachable origin as a visitor | Bot protection serves 403, 429, or a challenge |
| HTTP | One canonical 200 response after sensible redirects | Redirect loop, soft 404, or locale trap |
| Rendered content | Title, answer, links, and structured data exist in initial HTML | An empty app shell depends on client JavaScript |
Which crawler names need separate checks?
- Test retrieval crawlers separately from training crawlers because their roles and controls differ.
- Verify the final response body, not only robots.txt or the HTTP status.
- Audit representative page types: homepage, article, product, documentation, and a deep URL.
- Fix CDN and firewall rules before rewriting content; inaccessible pages cannot earn citations.
- Repeat the checks after deployments and monitor server logs for real crawler visits.
How do you run a repeatable crawler test?
- 1Choose representative pages
Select important URLs across each template and include at least one deep page.
- 2Read the applicable robots rules
Evaluate each official AI user agent independently, including wildcard rules.
- 3Fetch and compare responses
Record redirects, status, headers, body size, visible content, and structured data.
- 4Trace any block
Use edge and origin logs to identify the exact rule or rendering dependency.
- 5Retest and monitor
Verify the corrected response and watch for genuine crawler visits over time.
More questions answered
- Does allowing GPTBot also allow ChatGPT Search?
- Not necessarily. OpenAI documents separate agents for training, search discovery, and user-triggered retrieval. Audit and configure each current official agent according to the access you intend to grant.
- Why does an AI crawler get a 403 when robots.txt allows it?
- robots.txt declares crawl preference but does not bypass a CDN, firewall, authentication layer, or bot challenge. Inspect the edge event and origin logs to identify which layer returned the denial.
- Is a 200 response enough?
- No. A 200 can contain a challenge page, empty application shell, soft 404, or incomplete localized page. Inspect the returned HTML for the actual answer, canonical, links, and structured data.
- How often should crawler access be audited?
- Retest after changes to hosting, CDN rules, rendering, redirects, authentication, or robots.txt. For stable sites, a scheduled monthly check plus log monitoring catches most regressions.
- Should every AI crawler be allowed?
- That is a policy decision. Separate user-triggered retrieval and search discovery from model training, then allow or block each documented agent deliberately rather than using one blanket rule.
Want the full picture?
OptimAIze checks structured data, content, crawler access and answer-readiness to help you investigate concrete issues. Technical improvements do not guarantee AI citations.
Run a full GEO + AEO scan on your siteFrequently asked questions
- Why a separate robots.txt for AI?
- AI crawlers use distinct user-agents (GPTBot, ClaudeBot, PerplexityBot, Google-Extended, etc.). A regular robots.txt usually targets Googlebot only and silently allows or blocks AI crawlers — you should be explicit.
- Should I allow all AI crawlers?
- Choose permissions according to each crawler's documented purpose. Search discovery and model training can use different agents. Allowing a crawler does not guarantee citation, and blocking a training crawler is not the same as opting out of search.
- Will this hurt my Google ranking?
- No. Allowing GPTBot or Google-Extended doesn't change how Googlebot indexes you. Google-Extended specifically controls Bard/Gemini training, separate from Search.
- What about training vs answering?
- OpenAI documents GPTBot for model training and OAI-SearchBot for search discovery. Google-Extended controls specified Gemini uses, not inclusion in Google Search. User-triggered fetches may follow different rules; consult the vendor documentation before applying a policy.
Related free tools
Each one covers a different signal AI engines read before they cite a site.